Skip to content

Buggregator dashboard

I have ~350 tools running on Toolforge (and on-wiki scripts), so some years ago, I wrote a tool to rule manage them all. That included core to scour my talk pages (and my tools talk pages) on various wikis, github, bitbucket, codeberg, etc. for issue reports, keyword-guess (on wikis) which tool they belong to, and unify the issue reports. As it’s aggregating bug reports, I called it buggregator.

I recently thought about the various long-running Rust services I have running on Toolforge, including web pages with compute (e.g. PetScan), background jobs (e.g. Listeria), web APIs (e.g. wd-infernal), and both (Mix’n’match). These are different from the usual PHP-based webservices, which just spawn a script on demand, and forget about once it has run its course.

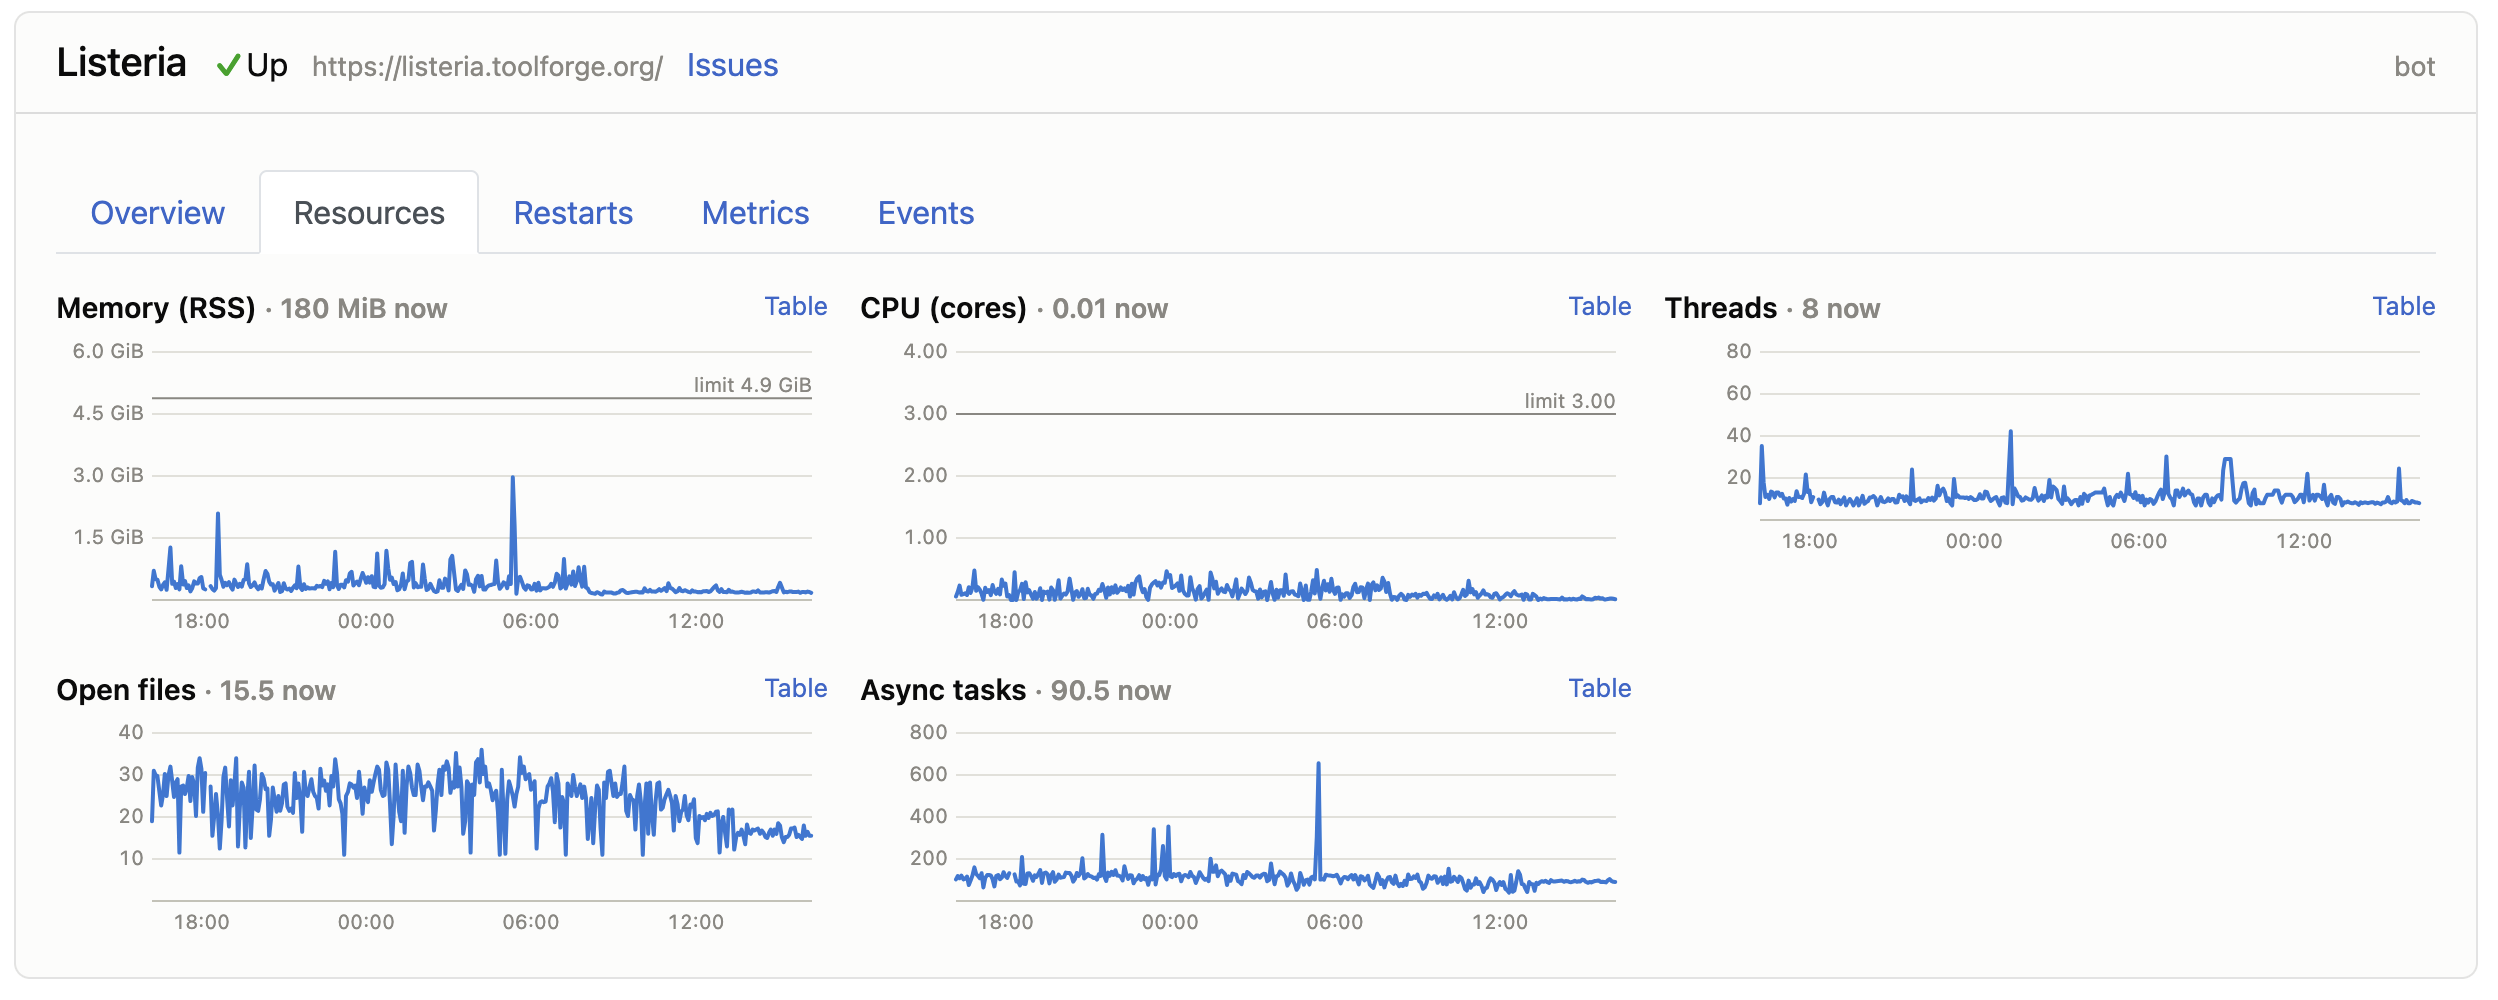
To keep an eye on the Rust services, I added a dashboard to buggregator. It tracks all 8 (9 if you count Mix’n’match webservice and background jobs as two separate ones) long-running Rust services, records minutely metrics, and logs restarts and their causes (manually/planned, out-of-memory, crash, killed by the Toolforge watchdog, etc.). It also shows a quick summary of the state of the services.

This is primarily for myself, but if you ever find a service of mine unresponsive, feel free to have a look.

BaGLAMa2 – Back to Business

BaGLAMa2 has been collecting view data for Wikipedia pages that contain image from a Commons category tree since March 2010. If your organisation “donated” images, audio, or video to Commons, this kind of data gives highly valuable feedback. Look, out images were viewed 20 million times on Wikipedia last month! There are over 1200 category tree “roots” in the database already.

However, this tool has had problems for a long time now, which started with Toolforge moving from grid computing to k8s. The initial version of the tool was written in PHP, and a single grid job would process one category tree and generate a TSV file. Later, I changed that to write all data directly to MySQL, resulting in a 20GB database, which did not scale well. Then I changed it back to storing the main data in files, sqlite3 this time. Meanwhile, the old TSV format and the MySQL data were both kept and supported. However, the k8s switch made the one-script-one-category approach impossible, and so I rewrote the tool in Rust, to run one single job To Rule Them All™. This worked in principle, but database connections and pageview API requests both did not scale well. I then tried a new, more efficient MySQL table approach, which also never took off. Sadly, BaGLAMa2 was stuck in a broken state for years.

Now, I tried a new, radically different approach (while staying in Rust, building on existing code).

First, I (and my useful slop generator) designed a new, bespoke, and highly optimized format to store results. As before, one file would keep the wiki sites, pages, images, and view counts for one category tree, for one month. However, where the dataset for a whole month would use something like 16GB (sqlite3 files, October 2022), the new format uses ~0.5GB in total for a month.

Then, I switched from using the pageview API, to reading the pageview data dump, which is conveniently available on the file system on Toolforge. All site/image/page data gets prepared in advance, which takes ~15min. Then, the compressed pageview dump file is read in its entirety, keeping the relevant view counts, which takes another 15 minutes. In contrast, the previous PHP or Rust processing took several days, and usually left some failed groups for re-run behind.

I have already back-filled July, August, and September of 2026. I have also converted all TSV and sqlite3 files to the new format. This has now saved almost half a TB of disk space on Toolforge. I will also convert the MySQL datasets into that format, to be able to retire the backwards-compatible reading (and writing!) code, and reduce the database size from 20GB to almost nothing. The total disk space for storing all BaGLAMa2 data will then be <35GB, with 0.5GB added every month. At this speed, it will take many decades to again occupy the space it did a few days ago, in the old formats.

Last not least, the new code will run automatically on the 3rd of each month, processing the pageview data from the previous month.

Reaping the harvest

Harvest Templates by User:Pasleim  has been a key tool for synchronizing data between Wikipedia templates and Wikidata. However, Pasleim stopped updating the tool in 2021, and issues have been piling up since.

So I (and my not-so-trusted slop generator) set out to Do The Thing: Rewrite it in Rust. And while at it, fix the issues that had accumulated. And implement the feature requests.

The rewrite it now live at harvesttemplates.toolforge.org, the source is on github (since Codeberg frowns at code that wasn’t written in the One Proper Way). Some highlights:

  • The “harvests” now run on the server, not in the browser, so they keep running in the background, can be paused, restarted, etc.
  • Much of what used to be API queries that would timeout is now done via the database replicas, so no more hanging “Loading…”, and huge queries work fine (though they can take a minute)
  • Editing will not add statements twice, which was a much-bemoaned issue. Also, HT now checks by default if that statement was ever removed before, and won’t add it again. Each row gets its own edit status, and won’t fail the batch. You can also preview edits as a dry run.
  • Now supporting qualifiers, coordinates, numbers with units, combining several parameters, values from nested templates, multiple properties per run, as well as PetScan, SPARQL, and instance-of filters
  • Your old permalinks, and the shares queries, have been ported to the new DB, so they will still work (when adjusted for the new URL path)

So, if you liked the original Harvest Templates, or got curious and want to try it out (there is a help page, and some examples), I hope you’ll give the new version a whirl.

The Issue Whisperer

There is a clear no to LLM-generated content on Wikimedia projects, which is a good thing IMO. On the other hand, I found that LLM-assisted coding helps me significantly in Getting Things Done as a volunteer, that would otherwise turn tools into bitrot graveyards over time. Given that LLMs can be useful for some tasks, I thought about an application for Wikimedia projects outside content writing and coding.

Many people write Wikipedia articles, but most do so in one or two languages.And, unless yours is a smaller language Wikipedia, one might not often read other language editions while writing. Wikipedia language editions are independent, so besides core information, they tend to focus on slightly different aspects of a subject. But what if they disagree on information? One of them might be outdated, or factually wrong. Even if both are correct, in their own way, seeing a conflict might lead to better writing, on both sides. And it would be essential to discover deliberately false information, on a Wikipedia taken over by compromised admins, as it has happened. It would also be beneficial to consider aspects and approaches on one Wikipedia edition in another; it might lead to a better article. That is not to say that all editions must say the same, but how do others do this is a classic source of learning, understanding, and improving, both your work and yourself.

So I asked Claude Opus to compare the language editions of a Wikipedia article. I picked the English, German, and French editions of Kassel, a city in Germany, as an uncontested topic. I told Claude to look for contradictions and important information missing in some editions. I also told it to produce a JSON file, and a human-readable table (below).

I believe even this little comparison is informative, and helpful for editors. Using more languages, and taking Wikidata into account, would make this even better. Of course, scaling up is not (financially) feasible with the commercially available LLMs. An open, capable LLM (e.g. Qwen series), ideally hosted on Wikimedia servers, would allow such comparisons, and other wiki-related tasks, for various tools. I am not talking about hosting a publicly accessible LLM, I am thinking of a back-end service for Wikimedia services, Toolforge, etc. It could be limited to access only Wikimedia sites, to avoid adding scraper stress to other websites. Either way, I believe there is potential in using LLMs to assist Wikipedia editors, if not the editing.

Claude comparison of Kassel, acrosss en, de, fr

English German French
Title Kassel Kassel Cassel (Hesse)
Depth Medium Very high (reference version) Low–medium
Character Strongest on dynastic history, WWII bombing, Anglosphere threads; stalest on present-day facts Deepest on geography, administration, religion, economy, local culture Declared partial translation of an old German revision — inherits German framing without German updates, but adds substantial French-perspective content

Core facts side by side

Field English German French Verdict
Population 201,048 (Dec 2020) in lead; 197,230 (2024) in table 197,230 (31 Dec 2024, state statistics); city’s own figure 207,863 200,406 body / 204,687 infobox Conflict
Area 107 km² 106.798 km² 106.78 km² Agree
Elevation 167 m (single value) 132.9 m lowest to 614.8 m at Hohes Gras 132.9 m to 614.8 m Complementary
Cassel → Kassel 1926 1926 in lead, “seit 1927” in history 1926 Conflict (internal to DE)
Etymology Several unproven assumptions Recent onomastics favours Germanic kas- + -sella Asserts Castellum Cattorum as fact Conflict
City rights 1189 deed certifies them; grant date unknown Before 1189; renewed 1239 by Hermann II Before 1189, renewed 1239 Complementary
Westphalia capital 1807 Occupied 1806, capital to 1813 Capital from 1806 Conflict
Worst air raid 90% of downtown, ~10,000 dead, 150,000 homeless; no date in body 22 Oct 1943, over 10,000 dead, 80% of housing Over 10,000 dead, over 80% of houses Conflict (scope)
documenta Every five years since 1955; latest 2022 Irregular at first, five-year cycle since 1972; text still ends at documenta 14 (2017) Five-yearly, 100 days, city-wide; 15th in 2022 Conflict
University 25,000 (2018) in lead; ~21,000 (2026) in body 23,699 (WS 2021/22); earlier university 1633–1653 ~25,000 (2018) Conflict
Fridericianum “Europe’s first public museum” First public museum building on the European continent “One of the oldest public museums in Europe” Conflict (claim strength)
Ice hockey Huskies dissolved 2010, successor in 5th tier Restarted, promoted to DEL2 in 2014 — Conflict (EN stale)
İzmit twinning not captured 2000 1999 Conflict

Sharpest contradictions

# Issue Assessment
C1 Population spread of ~10,600 across editions Not a factual dispute but an undeclared definitional one: census-adjusted state statistics vs. the municipal residents register. Only German tells the reader both exist.
C3 English geography section places Hesse in “the south-western part of Germany” Flatly wrong, and contradicts English’s own lead (“central Germany”) and the German/French statement that Kassel is about 70 km north-west of Germany’s geographic centre.
C2 Fama Fraternitatis: 1617 (EN) vs 1614 (FR) 1614 is the standard dating of the first printing; English looks like an error.
C5 Student numbers Real enrolment decline reported at three vintages, plus an English lead never reconciled with its own body.
C13 Scheidemann as mayor: “1920 bis 1925” in prose vs. 1919–1925 in the mayors list Internal German inconsistency.
C15 English still lists Bombardier as a local employer Absorbed by Alstom in 2021; German notes Alstom on the site.

Substantive content in one edition only

Topic Only in Why it matters
WWI POW camp at Niederzwehren: built for 20,000, extended to 30,000, and a 1915 typhus epidemic in which a French army doctor estimated roughly 12,000 of 19,000 prisoners infected and 2,300 dead by end of June — 1,600 French, 700 Russian; other sources say 3,000 FR The largest unique block anywhere. Absent from German entirely.
Hesse-Kassel selling Hessian soldiers to Britain to suppress the American Revolution, financing palaces and the landgrave’s lifestyle EN Central to 18th-century city finances; missing from German.
SA and SS in civilian clothes wrecking the synagogue on 7 November 1938 to fake spontaneous anger, two days before the national pogrom; 2,301 Jews in 1933, ~300 refounding the community, ~1,300 by 2006, new synagogue opened 28 May 2000 DE English says only that “in the late 1930s, Nazis destroyed the Kassel Synagogue” and nothing about afterwards.
GDP of €9.914bn (2016), €49,937 per capita against €43,496 for Hesse; unemployment 10.2% (2011) → 6.7% (Dec 2018); city entered Hesse’s municipal rescue scheme in 2012 and left in 2016 DE English offers one unsourced sentence about halved unemployment.
Treppenstraße (1953) as West Germany’s first pedestrian street; first German city to introduce the parking disc (1961); reconstruction following plans drawn up under the Nazi regime DE The reconstruction-plan provenance is a real historical point, not trivia.
First German observatory (1558); documenta 6 making Kassel the first city lit by laser at night (1977) EN —
Napoleon III imprisoned at Wilhelmshöhe after Sedan; Hindenburg and Ludendorff preparing the capitulation there in 1918; Brandt–Stoph inter-German talks in 1970 EN French omits the imprisonment of a French emperor while detailing French POWs.
Kasselänerisch dialect; the Kasseler / Kasselaner / Kasseläner distinction; and that the cured pork called Kasseler is not from Kassel but named after a Berlin butcher named Cassel DE Exactly what a non-German reader would want and won’t find in English.
Kassel’s boundaries unchanged since 1936, because the 1970s Hessian reform brought no incorporations DE Makes the population series directly comparable over time, unlike most German cities.
German Rugby Federation founded in Kassel in 1900; first German water-ski club 1949 and federation 1958; MT Melsungen playing Bundesliga handball in the Rothenbach-Halle DE English covers only football and ice hockey.
Brothers Grimm resident 1805–1830 as court librarians; Druselturm dated to 1415; 1923 Esperanto congress under Einstein’s honorary presidency FR The Einstein item is unsourced in French.

Mix’n’match search buttons

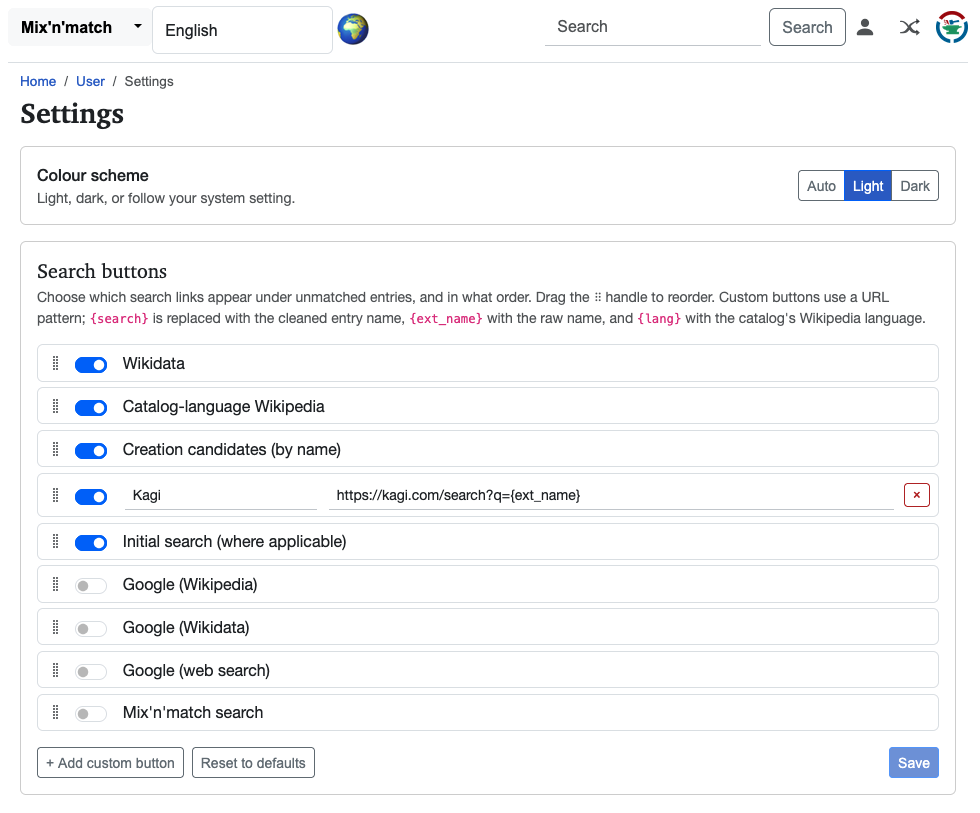
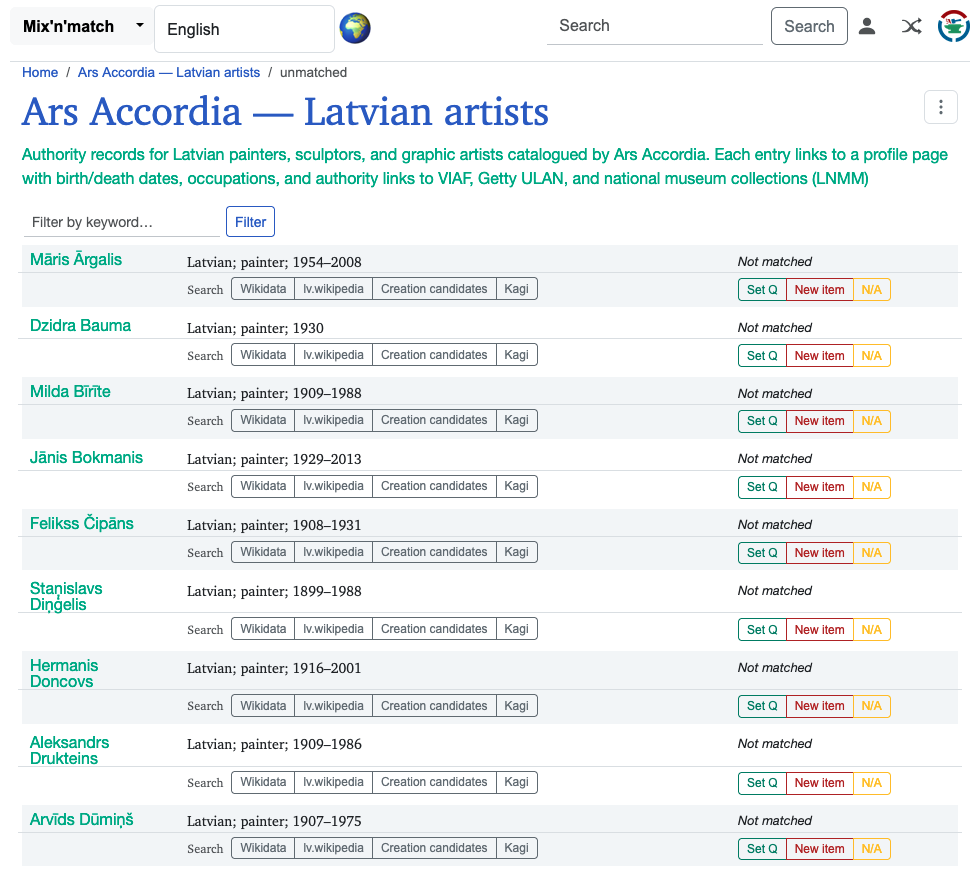
A brief update on Mix’n’match. When you are logged in, you can reach your “user page” in Mix’n’Match through the user icon in the top navbar. On that page, you will now find a link to “Settings”. The first setting (besides dark mode) there is a configuration of the search buttons on unmatched lists of entries. This doesn’t sound like much, but I found that looking for an entry in a bespoke search engine, or in the Mix’n’Match “creation candidates”, is very helpful.

Freeform statements

My Mix’n’match tool has a little-known feature that I think deserves a little attention.

A catalog in Mix’n’match is a list of entries in other datasets that should be matched to Wikidata. Besides some required core data for each entry, the user importing the catalog can add key-value-pairs for Wikidata statements that can help to match the entry (e.g. VIAF ID), or can be nice-to-have for item creation (e.g. occupation).

Now, many datasets contain such additional information, but often in free-form text. That person here was born in Berlin – but is it the Berlin in Germany, or the one in New Hampshire? This often depends on the context of the dataset. This makes conversion from free-form text to proper Wikidata IDs difficult and time-consuming, and a hurdle before import into Mix’n’match. So often such data gets thrown away.

But there is another way: If you know the Wikidata property for a “factoid” in your dataset (e.g. “place of birth”), you can import it as a “statement text”. It is still a key-value-pair, but while the key is a Wikidata property ID, the value can be anything you like.

So that “statement text” is now sitting in the Mix’n’match database (~1.4 million rows, at the time of writing this). But what can you do with that? You can convert it to “normal” auxiliary statement data via a handy web interface! But wait, do you have to do this for every single “statement text”? Not necessarily! As it turns out, within a catalog and a property, there are often repeat values. As you can see in the video, a taxon rank called “form” is used over 300 times in this catalog. In this context, they all refer to the same thing. Search results for this value are presented to you, and in this case, it happens to be the first hit on the list. One click, and all 328 taxon ranks are converted into the appropriate Wikidata item value.

The link to “statement text” in the action drop-down will appear only if the catalog has any (unmatched) statement text for you to work on. So, feel free to import free (-form text) with your next catalog!

WikiFlix updates

WikiFlix is one of my tools that got some press when it started, but had stalled a bit due to lack of development. Thanks to recent developments, I was able to pay some attention to it again.
First, there are a lot of invisible changes to the code itself, moving the front-end to refactored ES6 JavaScript, and making the hourly update job more efficient.

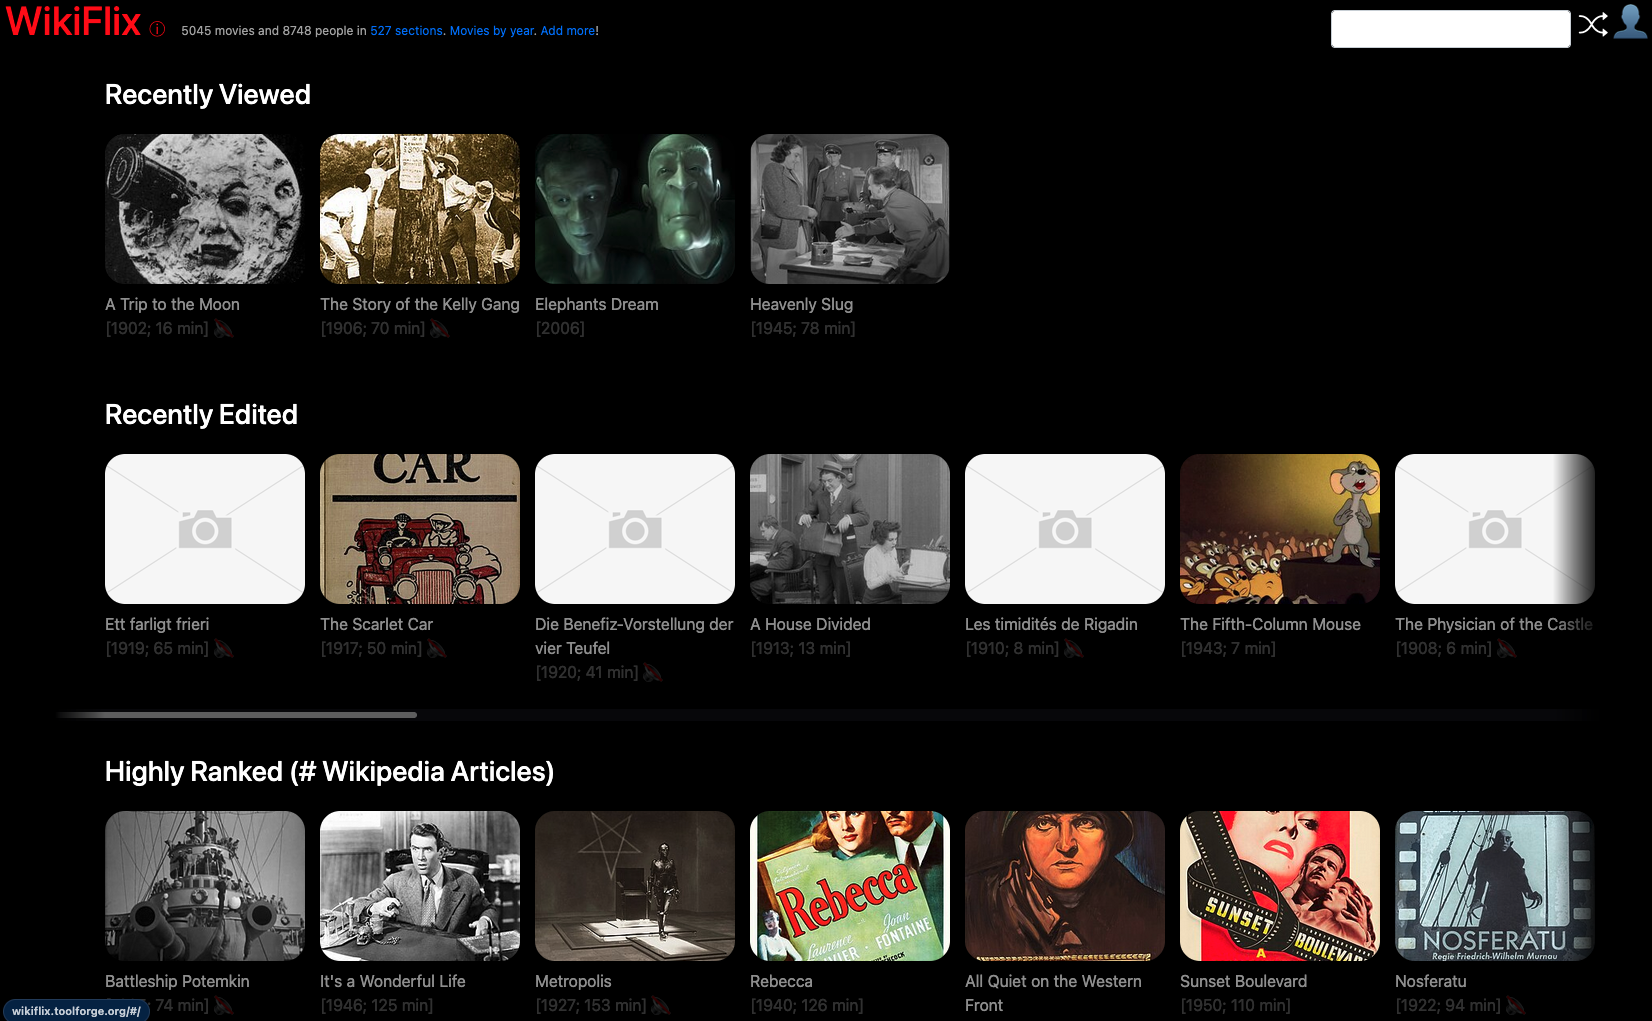
On the visible side of things, there is a new “Recently viewed” section that is stored in your browser only, so you can remember and resume recent movies. The “special sections” (e.g. “Highly ranked”, “Female directors”) are now clickable, leading to the full respective list. The lists themselves are now loading more entries on scrolling, rather than loading all of them at once, making for a faster, smoother experience. Several pages now show initial “placeholder boxes” that are filled when loaded, which makes a for less jarring experience than “blank page, stand by”.

The search box is now more prominent, and there is a “random movie”button, if you are bored. Also, playing a movie (Commons, YouTube, Internet archive) will now immediately launch a full-screen player, which is what I suspect most people would prefer over the page-with-iframe.

Finally, I am now including a more edge cases of movies (e.g. “Public domain in the United States” rather than just “PD”). This pushed the movie count to 5100.

Update: I now added free TV episodes as well, pushing the count to over 5200. Example series: Calvin and the Colonel

A little controversy

This is going to be controversial, so I would ask you to reserve judgement until the end of this post (with the average internet crowd, such an appeal would be pointless, but people who read this blog are usually familiar with the NPOV concept, so I have hope).

I have been writing code for over 40 years. I have worked in the usual (and some unusual) programming languages. I can work “full stack”. I wrote the original version of MediaWiki during a semester holiday 25 years ago, and I have been writing MediaWiki-related code ever since. This is not to brag, but to set the stage.

With over 350 tools juggled in the air as a hobby, I find that I can keep the big ones running, and occasionally I find time for a new one, or a rewrite. But all of that code is technical debt, and it’s slowly rotting away. And while my tools usually work, they are often written organically, growing into strange shapes as time passes and features are added.

That makes most of my tools difficult to maintain, even for me. Passing a tool to someone else to take care of is… difficult at best.

I had looked into LLMs (mostly ChatGPT at the time) for coding when it first came into fashion, so to speak, but the results were spurious and, frankly, unacceptable. Then, about half a year ago, I played around with Claude Opus again, and it was… better. Around the same time, I was notified that one of my oldest tools, “geohack”, was exhausting its assigned Toolforge resources. As many of you know, I like to experiment, so I told it to rewrite the PHP codebase in Rust (vibe-transpiling?). The result was astonishing. Even though I told it in no uncertain terms to reproduce all details of the original code, I would never have expected it to spit out an essentially feature-complete, fully working version.

Yes, I am quite capable of doing this work myself. For example, I have previously rewritten CatScan (PHP) into PetScan (C++) into PetScan (Rust). But to do that, I would have had to drop other things, for quite a while. And it would have been quite tedious. This way, I had it done in an afternoon. Was the code good? Kinda. But I was very specific about sacrificing style for faithful reproduction of functionality, so that’s OK. I could probably outsource part of it to an existing Rust crate. But it works well as it is, much better than the original.

Finally, there was hope for me to get my tools at least to a maintainable level. I started asking Claude to refactor, write tests, find bugs (and it did, including potentially security-relevant ones), move the codebase towards SOLID and DRY principles, reduce cognitive complexity, use best practices and language standards — all things you would want for your code. I did this with Rust codebases first, since the stringent but helpful compiler works very well at pushing back against LLM-induced issues, but eventually I expanded into PHP and JavaScript territory.

An incomplete list of things I had Claude help with:

Is that “vibe coding”? I don’t think so (that would be more like “go write a banking app in assembler, YOLO!!1!”), but call it whatever you like. Is the code “slop”? It does have a different “taste” from my own code. It can be a bit verbose. But given the upsides of using LLMs, especially with the directives I put in place (writing tests, SOLID/DRY, etc.), the codebase as a whole is more accessible. And with very few, small exceptions, I have never had Claude write a de novo codebase (transpiling from PHP is mostly mechanical, so it doesn’t count in my book), so I am iterating on my own code, and actually reducing lines of code (e.g. merging the Mix’n’match PHP code into the Rust one) that I need to maintain. Of course, new features require new code, but that is true of all coding, and I try not to go overboard.

So am I an “AI” fanboy now? Most certainly not. Likewise, I am not apologetic about using it. It is a technology that has helped me. Using LLMs has improved my tools, both at the code level and in the user experience. That is a win in my book. I would love to have a little box with a copy of Claude (or similar) on my desk as a permanent assistant (usage is not cheap!), but if LLMs get outlawed tomorrow, go bankrupt, or increase prices even more, I will shrug and move on. I’ll be fine without it. At least I got some use out of it while it lasted.
Tools United

Some of my tools are JavaScript scripts on Wikidata. They are added by users on their commons.js page and run in their web browser when browsing Wikidata. I have about a dozen of them, of various ages. Some of them I had updated four years ago, and put a “shared library” sort-of-thing in place.

One thing that always happens with these scripts is that I start developing them in a nice editor on toolforge, but once they reach a certain maturity, I put them on a Wikidata “code page”, announce them, fix the inevitable bug or two, and then leave them be; it is too awkward to copy them into the Toolforge file again, switch the include to Toolforge, work on it, and then switch everything back, just to be able to edit in a decent editor.

Using my own scripts on a daily basis, I had accumulated a few things that bugged (see what I did there?) me, and I decided to do something about it. And then I paused and did something bigger. I took my “shared library”, and the (still working) scripts, and put them in a repo on codeberg. I also wrote a Python script that can sync between Wikidata and the local repo. I can now use my trusty editor (Zed) to edit files, push them to repo, and to Wikidata, with one line. I also put a decent README that briefly describes the tools. As a side effect, I now offer the issue tracker to file bug reports and feature requests; I hope this gets take up over “adding it to some talk page” where it is too easily forgotten.

Now, what did I do with this awesome power? Mostly things behind the scenes. One visible change is how statements get added to the Wikidata interface (DOM). Until now, I just added statement-lookalike boxes as placeholders, but they were just Potemkin’s <div>s; they could not be edited, had no references, no new references could be drag’n’dropped on them, etc. Now, I am using the (officially undocumented) Wikibase JS functions to add new statements, so they become not only visible immediately, but are working, usable members of the statement society, as if I had added them manually, with keystrokes, like some caveman. And if this undocumented hack ceases to function one day, it will just fall back on the previous, display-only version.

I hope this will future-proof the scripts, at least for a while, and maybe even tempt others to use the “shared library” in their own scripts.

All about the images

I have a collection of tools around images (or these days files in general) and their use on the various Wikimedia projects, that run under a single Toolforge tool name. These are:

  • FIST, the Free Image Search Tool, where you can find images for Wikipedia articles on various sources, including Commons, Flickr, the Internet Archive, Nasa etc.
  • WDFIST, to find images on Commons to use on Wikidata
  • WD4WP, to find images used on Wikidata that could also be used on Wikipedia articles that lack an image (example: German Wikipedia)
  • File Candidates, a collection of files from both Commons and Flickr that could be used in Wikidata items, but were automatically gathered beforehand (e.g. taxonomic species)

These tools have been around many years, with FIST predating Wikidata. They were in various states of decay, WDFIST holding up best, the original FIST tool a broken PHP script. So I thought to bring them up to date a bit.

FIST was completely rewritten into FIST2. File Candidates was absorbed into WDFIST as a way to find candidate images. All tools were upgraded to use Vue2 ES6 JavaScript modules. They now share common, reusable components, and a common visual language. And all of them should work better on mobile, especially WDFIST. Also, all tools are hardened against the recent Wikimedia API rate limits, with automatic retries, and keeping API queries to an absolute minimum. I hope that these refurbished tools will be of use to people, so happy (re-)discovery!